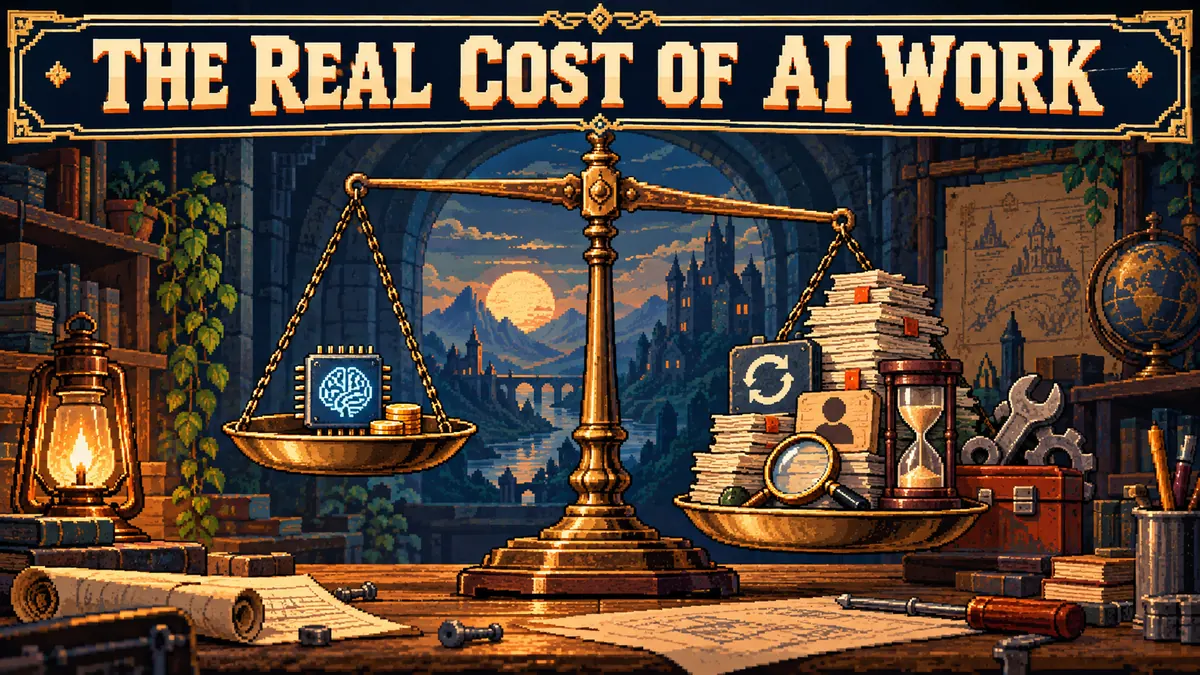
That cheap model call is not the cheapest part of your AI feature. The expensive part is explaining the answer it got confidently wrong.
The bill is the visible part
A model API gives you an invoice, and invoices are easy to count. But a product feature costs the time spent writing prompts, building retrieval, measuring bad answers, handling retries, and maintaining the integration when the provider changes its behaviour.
There is also the review queue. If a person needs to check every generated summary for unsupported claims, the product's cost includes that person's time. The feature may still be worthwhile, but compare the full task before and after AI instead of treating tokens as the whole budget.
Make a rough cost model
Estimate total expense over a representative batch, such as one hundred user requests. Include model usage, search or tools, retries, human review, and repair. Track a range, not a false-precision number: the slow tail of requests and the hardest failures can dominate the user's experience.
| Measure | Count per 100 requests | Why it matters |
|---|---|---|
| Successful outcomes | Completed to your quality bar | Useful output, not just output |
| Model and tool spend | Calls, search, compute | Direct running cost |
| Retries and timeouts | Repeated attempts or failed runs | Reliability and hidden expense |
| Human review minutes | Inspection and corrections | Operational cost |
| Harmful false successes | Wrong output accepted without detection | Risk that averages conceal |
Measure before you scale
Collect normal tasks and failure-prone cases. Run a baseline workflow and the AI-assisted workflow with the same input. Record completion, correctness, latency, and review time. A language model that is slightly worse but much faster may fit a low-risk brainstorming task. It might be unacceptable in an action that sends money or changes an account.
Track uncertainty. One hundred requests from a few friendly testers can miss the uncommon but consequential case. If the system acts externally, count and review every action while you are still learning its behaviour. Gate actions behind confirmation until you know what mistakes it makes.
Know when to keep the feature
An AI feature earns its place if it measurably improves a task someone wants to complete, with failure costs and maintenance that are acceptable. The improvement could be less waiting, access for a user who could not do the task before, or a better first draft. It does not have to make every metric better.
If a fixed rule, search box, or template handles the task more consistently, use the boring tool. You can keep the model for cases where flexible language matters. Product judgement includes knowing when a feature's demonstration is more impressive than its day-to-day value.
When you do ship it, keep a change log, a representative regression set, an owner, and a way to fall back. That is how an interesting prototype becomes a tool somebody can rely on.
FOLLOW THE EVIDENCE
Sources & further reading
Process note: AI tools assisted with research and drafting. Sources are linked so you can inspect the evidence. Unless an essay says otherwise, it does not claim hands-on testing or independent reproduction.