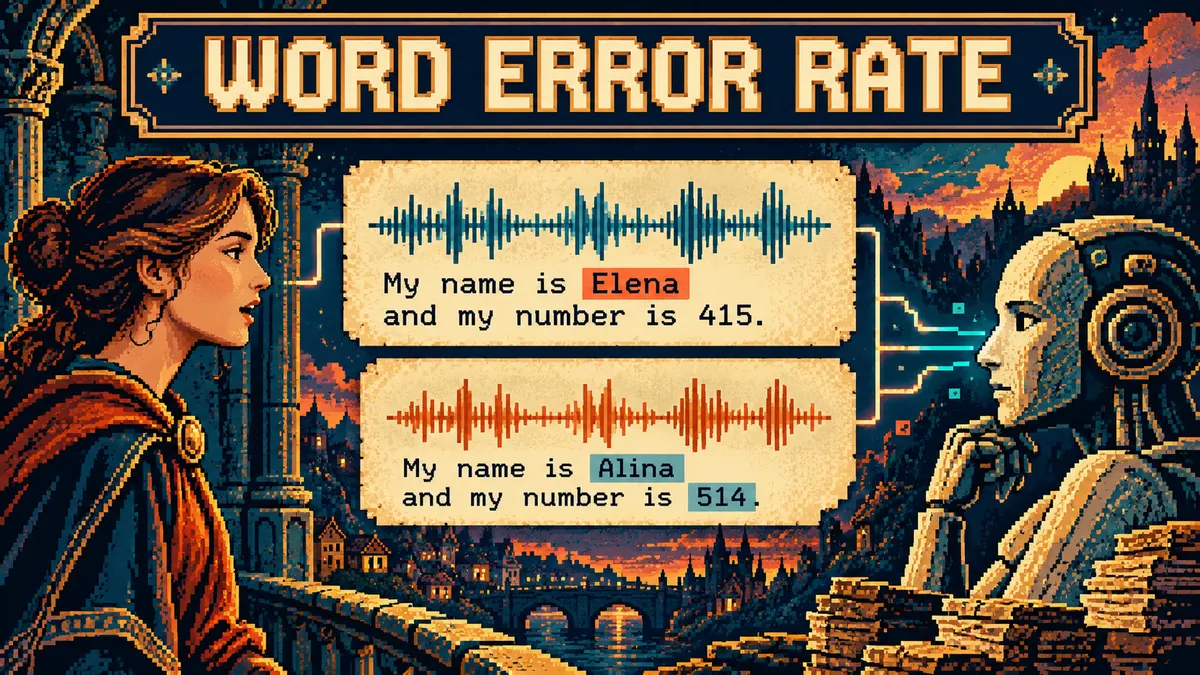
A speech recognizer can make a small number of word errors and still get the only important number in your instruction wrong. The aggregate score cannot tell you which failure happened.
A useful definition with a sharp boundary
Word error rate measures insertions, deletions and substitutions between a reference transcript and a hypothesis. Sum those edits and divide by the number of reference words. It gives speech recognition experiments a common yardstick and is easy to compare across datasets when text normalization is consistent.
But a single edit is a single edit regardless of consequence. A filler word and a changed dosage, account identifier or meeting time can affect the score similarly. Punctuation may not count under one normalization scheme and may matter to a downstream task. WER cannot be used as a complete measure of usefulness without understanding what kind of mistakes are inside it.
Before comparing two systems, inspect how the references were normalized. Are contractions expanded? Are numbers words or digits? Are partial words, disfluencies, case and punctuation ignored? A mismatch in text rules can make an apparent model difference partly an evaluation difference.
Score the errors your user notices
Build categories that reflect your task. Proper names, product terminology, quantities, negation, speaker attribution and words that trigger downstream action deserve separate counts. You can preserve aggregate WER and report a critical error rate alongside it. A useful product may tolerate more harmless cleanup if it makes fewer damaging errors.
Audio also changes the result. Compare phone microphones with laptop microphones, overlapping speech with one speaker, close-mic speech with a distant room, clean audio with background noise, and the accents your users actually speak. Do not label a model 'bad on accents' based on a handful of examples. Gather enough examples, describe the group and report uncertainty.
For Phonon-2, the published seven-set average is a helpful reference point for English recognition. A team evaluating it for local meeting transcription should still test meeting recordings, expected vocabulary and available hardware. It is inappropriate to infer multilingual performance from an English score.
| Error class | Example impact | Evaluation improvement |
|---|---|---|
| Numbers | A cost becomes $50 instead of $15 | Score numerals and quantities separately |
| Names | The wrong person is assigned an action | Build a names and terminology subset |
| Negation | 'Did not approve' becomes 'did approve' | Measure semantic or action-critical flips |
| Speaker attribution | The decision is assigned to the wrong person | Check diarization and transcript together |
| Punctuation and timing | Caption breaks obscure the meaning | Include timestamp and readability review |
Create a small but honest audio set
Start with consented recordings from the actual environment. Write references consistently and record which microphone, language, room and task produced each clip. Include ordinary examples as well as the difficult cases that appear often enough to matter. Never use private recordings simply because they are available on somebody's laptop.
Keep the test set separate from the audio used to tune vocabulary or choose settings. If you repeatedly adjust the system after looking at every result, the score stops being an independent estimate. Keep a development set for improvements and a held-out sample for the final check.
Run each engine with the documented settings. Save the transcript and version. A score you cannot reproduce is not useful when the model updates next month.
Quality is only one deployment constraint
For live dictation, measure time from the end of speech to the first useful text and the distribution of delays, not only audio processed per second. For a file archive, measure total throughput and memory. For captioning, measure timestamp quality. These are different user goals and deserve different test metrics.
Local inference can keep audio on a device, which reduces one important exposure route. Verify whether your app sends telemetry, backs up audio, downloads models, or calls a cloud service through another feature. 'On-device model' is not synonymous with 'the entire application never sends data'.
Use a pre-deployment run that includes setup time, cold start, failure recovery, battery use where relevant and the user-visible correction flow. Choose the system that fits the actual task and sensitivity. A leaderboard is a shortlist, not your production sign-off.
FOLLOW THE EVIDENCE
Sources & further reading
Process note: AI tools assisted with research and drafting. Sources are linked so you can inspect the evidence. Unless an essay says otherwise, it does not claim hands-on testing or independent reproduction.